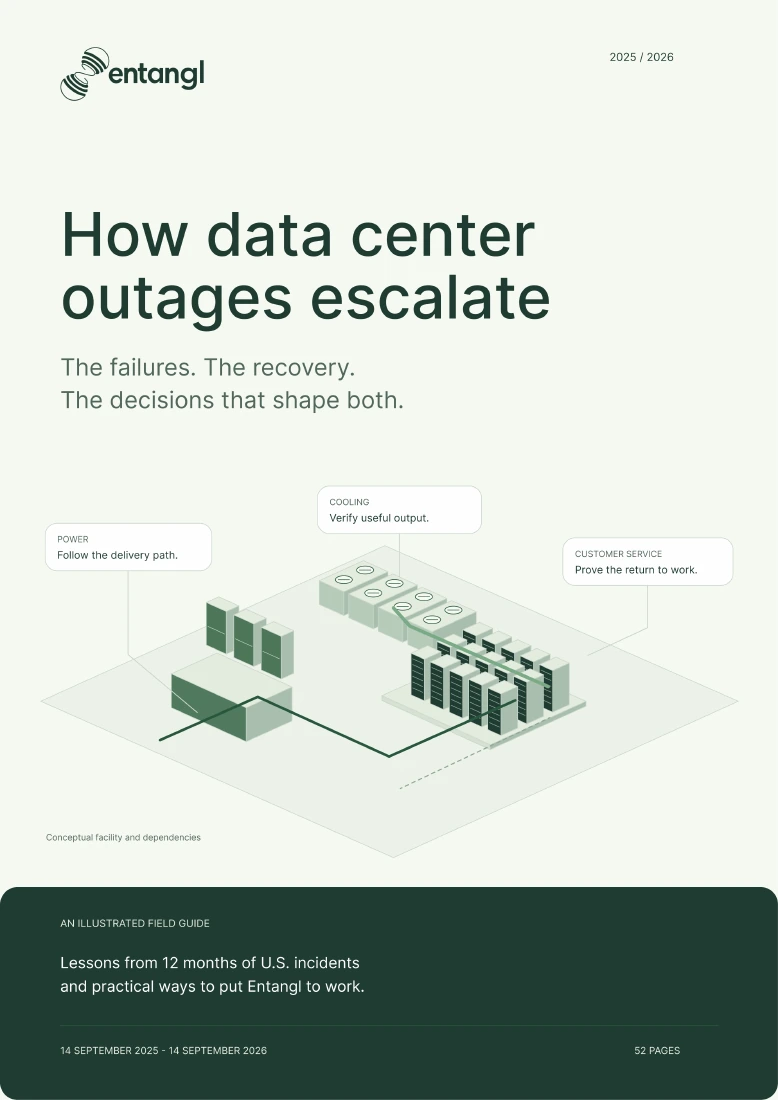
How data center
outages escalate.
The failures. The recovery.
The decisions that shape both.
Our annual data center outage report follows 12 months of U.S. incidents, from the first failure to the return of service. See what happened, why recovery took longer, and what to review at your own sites.
- Pages
- 52
- Detailed cases
- 9
- Months of incidents
- 12
14 September 2025 – 14 September 2026
Read the failure.
Follow the recovery.
Nine detailed cases draw on incidents involving Microsoft Azure, Google Cloud, Nebius, AWS / Coinbase, and Blacksmith.
- 01
See how the failure spread.
Illustrated case studies trace power, cooling, network, and shared infrastructure failures.
- 02
Understand what delayed recovery.
Follow the dependencies, handoffs, and restart decisions between restoring a facility and restoring service.
- 03
Take the questions back to your site.
Review scope, sequence, equipment state, monitoring context, and recovery with your team.
Public sources.
Practical operating lessons.
Based on operator and customer post-mortems, status histories, company statements, and other published sources. The report includes a broader register of 32 reports and leads. It is a selected evidence base, not a count of every outage in the industry.